At Edifice, the AI feature that rewrites text in FALC (Easy Read) went from 34% to 79% satisfaction in a few months. Thanks to a Screeb survey displayed right after each generated text, the product team measured what users think, adjusted the prompt and the LLM, and got 100% hosting in France approved for the public sector.
An AI feature isn't judged by how often it's used, but by what users think of what it produces. Edifice verified this with Screeb: the satisfaction rate of its rewriting assistant, built on the FALC technique (easy to read and understand), went from 34% in June to 79% in early October, by adjusting the prompt and the LLM based on feedback.
Edifice publishes educational platforms used by primary and secondary schools across France. Romain Gentet, Lead Product Manager at Edifice, set up the measurement system. He explains how a simple survey, displayed a few seconds after each generated text, let the team know what worked, what people disliked, and in which direction to correct the AI.
Why measuring AI satisfaction changes everything
With a conventional feature, you know what it will produce: the result depends on an algorithm you control. With generative AI, the result varies from one use to the next, and its quality is partly subjective: a text can be correct on paper and still not suit the person who has to publish it.
For Romain, the issue isn't that measurement gets harder, it's that it becomes more important:
“I wouldn't say an AI feature is harder to measure. Of course there are always the usual service quality metrics, but measuring satisfaction matters more because you don't know exactly what the AI is going to produce, the way you do with a more algorithmic, conventional feature. The iterative approach seemed more relevant to me right away, and also a good way to get to production faster.”
— Romain Gentet, Lead Product Manager, Edifice
The Edifice case: an Easy Read AI to speak to every family
Edifice publishes educational platforms that regions and departments use to communicate with families. In Hauts-de-France, the platform covers the region's middle schools, high schools and primary schools, an audience of around 400,000 parents.
For these institutional messages, Edifice built into its text editor an AI rewriting feature inspired by FALC, “facile à lire et à comprendre” (easy to read and understand), an inclusion approach of European origin. The author writes their text, and the AI suggests a simpler version. It has been in production since March 24 in Hauts-de-France, and has since been rolled out to the other platforms.
The challenge comes down to two things:
- Acceptability: the suggested text has to convince the person who will sign and send it.
- The prompt: the text needs to be understandable, without overly choppy sentences, in the service of inclusion.
For this type of message, there's no way to know whether the AI holds up without asking the people who use it.
The setup: a Screeb survey right after the generated text
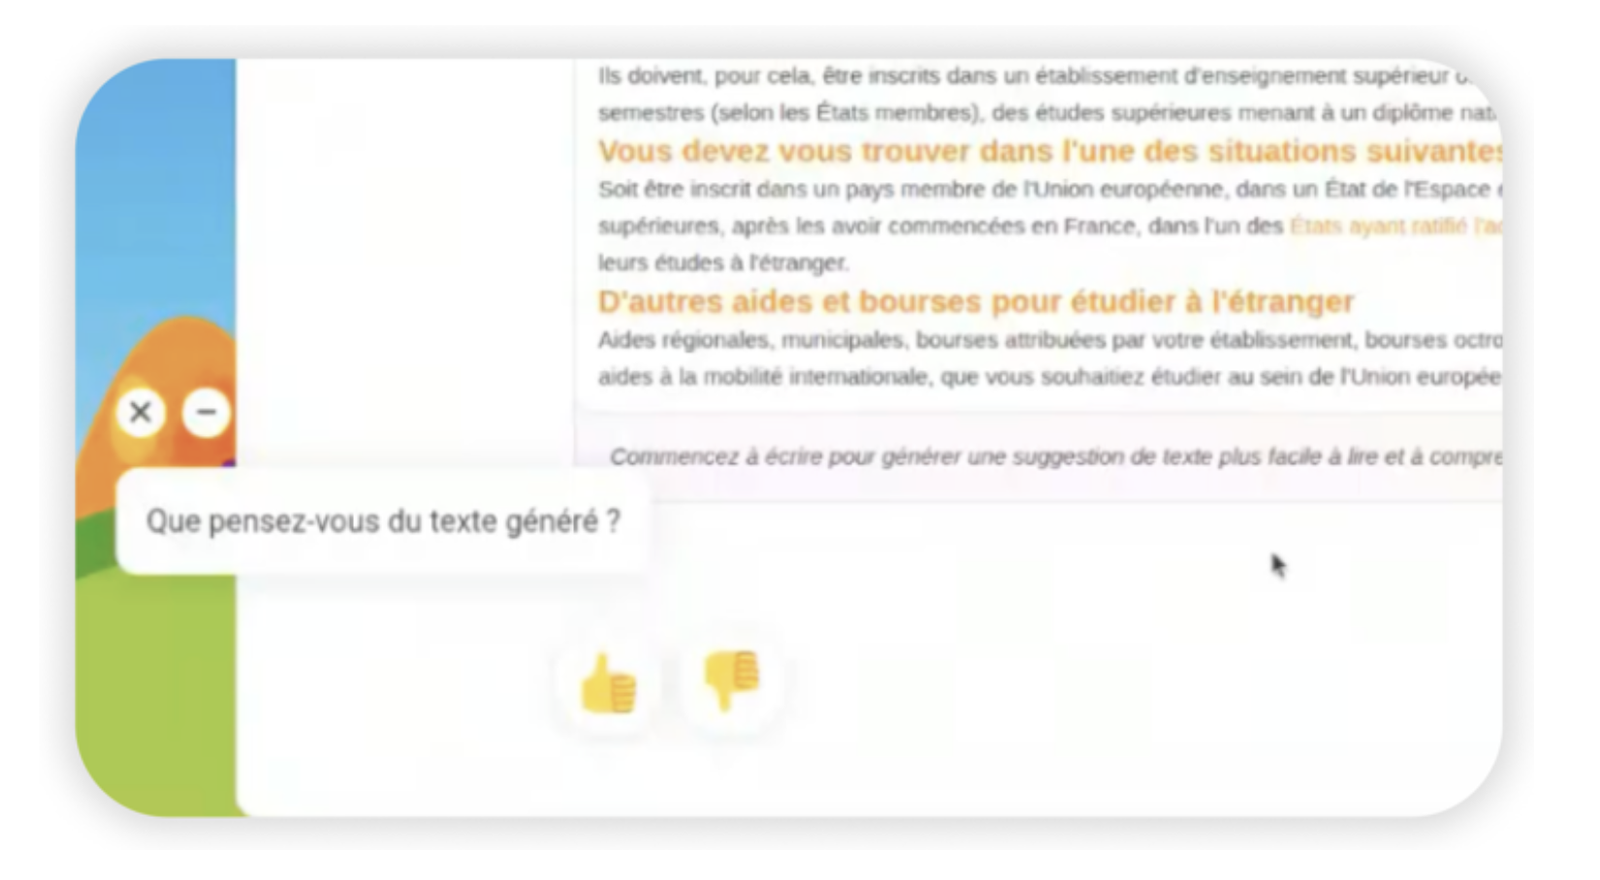
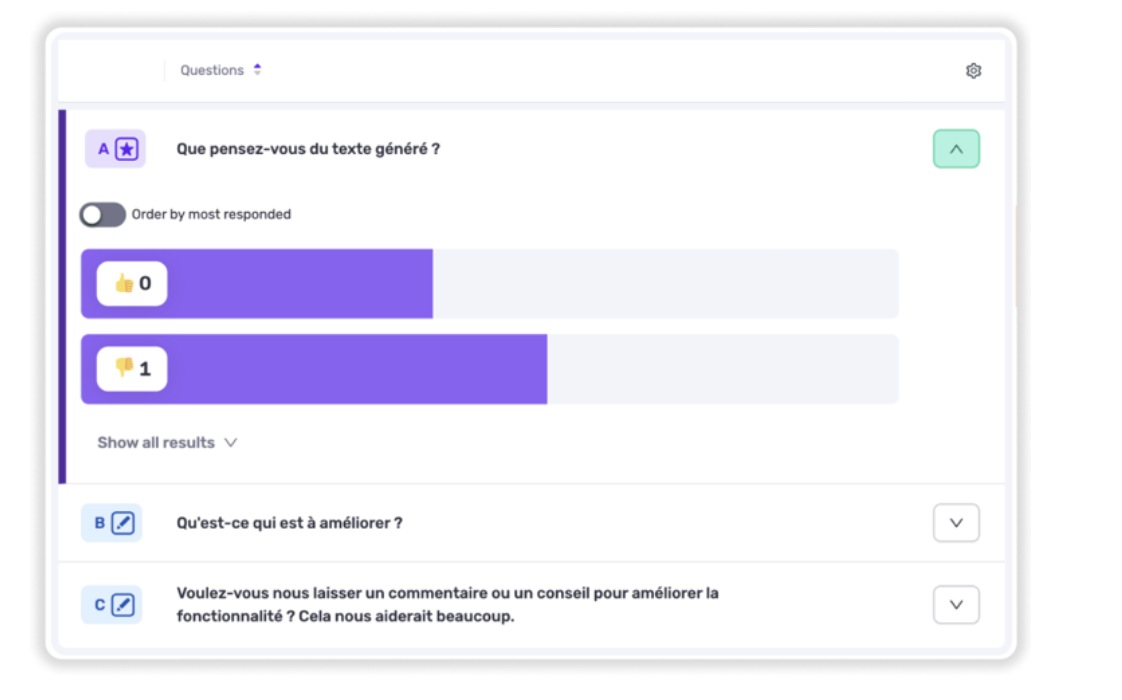
Edifice configured a short in-app survey in Screeb that appears in the application about 10 seconds after the AI returns its text. It asks a first question, “What do you think of the generated text?”, with a thumbs up or a thumbs down. Two open-ended questions follow: “What could be improved?” and a free comment.
The right moment: right after the text has been read
The trigger is the decision that matters most. Romain explains it this way:
“It seemed more relevant to me to do it right after the suggested text is read, to get a better response rate and feedback that's as fresh as possible, so the input on the wording is as relevant as possible. Also, users need to clearly see what the survey is about, because we have dozens of other features in the platform. An asynchronous form was less suited to this case.”
— Romain Gentet, Lead Product Manager, Edifice
A questionnaire sent later would have asked users to remember one text among dozens of uses. Here, the question arrives when the opinion is freshest.
A format that limits friction
According to Romain, the thumbs up or down followed by two open-ended questions was a way to generate as much engagement as possible in the survey flow with a simple question. It's also a pattern that is starting to take hold in AI rewriting features: users are used to it, which reduces friction even further.
The before and after text, attached to each response
The survey doesn't just return a score. Edifice collects, in pseudonymized form, the text entered by the user and the version suggested by the AI, attached to their response. This feedback is then exported to an agent that runs a semantic analysis, to check that the rewriting holds up against what users say.
So when a thumbs down comes in, the team can read what the user had written, what the AI returned, and what they think of it.
What the feedback taught the team
From the first weeks, the feedback highlighted a recurring area for improvement: the tone, judged too familiar. Comments were short and concrete, like “too familiar,” “the register” or “the formal you.” The same finding came up in parallel through a client department, for which the formal “vous” is a recommendation from the French Ministry of National Education.
Formality that depends on who is writing
By reading the texts before and after, the team understood that the expected register wasn't the same for everyone:
“We realized that the expected formality could depend on the type of communication and the profile of the user. A school principal will expect a more formal text. A teacher, when communicating in general, usually adopts a friendlier tone.”
— Romain Gentet, Lead Product Manager, Edifice
First surprise: teachers used the feature more than expected, even more than school principals, for their internal communications. So the unsuitable tone wasn't only a matter of improving the prompt, but also of the user's profile and audience.
Iterating on the prompt and the model
For Edifice, the rise in satisfaction comes from a series of adjustments to the prompt and to the LLM used behind the feature. The feedback helped find the balance between the FALC format and how users actually work, with a good reason to move by trial and error: each version could be tested, then validated or dropped based on data rather than intuition.
This is where Screeb changes the way of working: the team decides with real data, surfaces metadata useful for analysis and saves time to test and iterate.
Results: from 34% to 79% satisfaction
Satisfaction measured by the survey went from 34% in June to 79% over the first half of October.
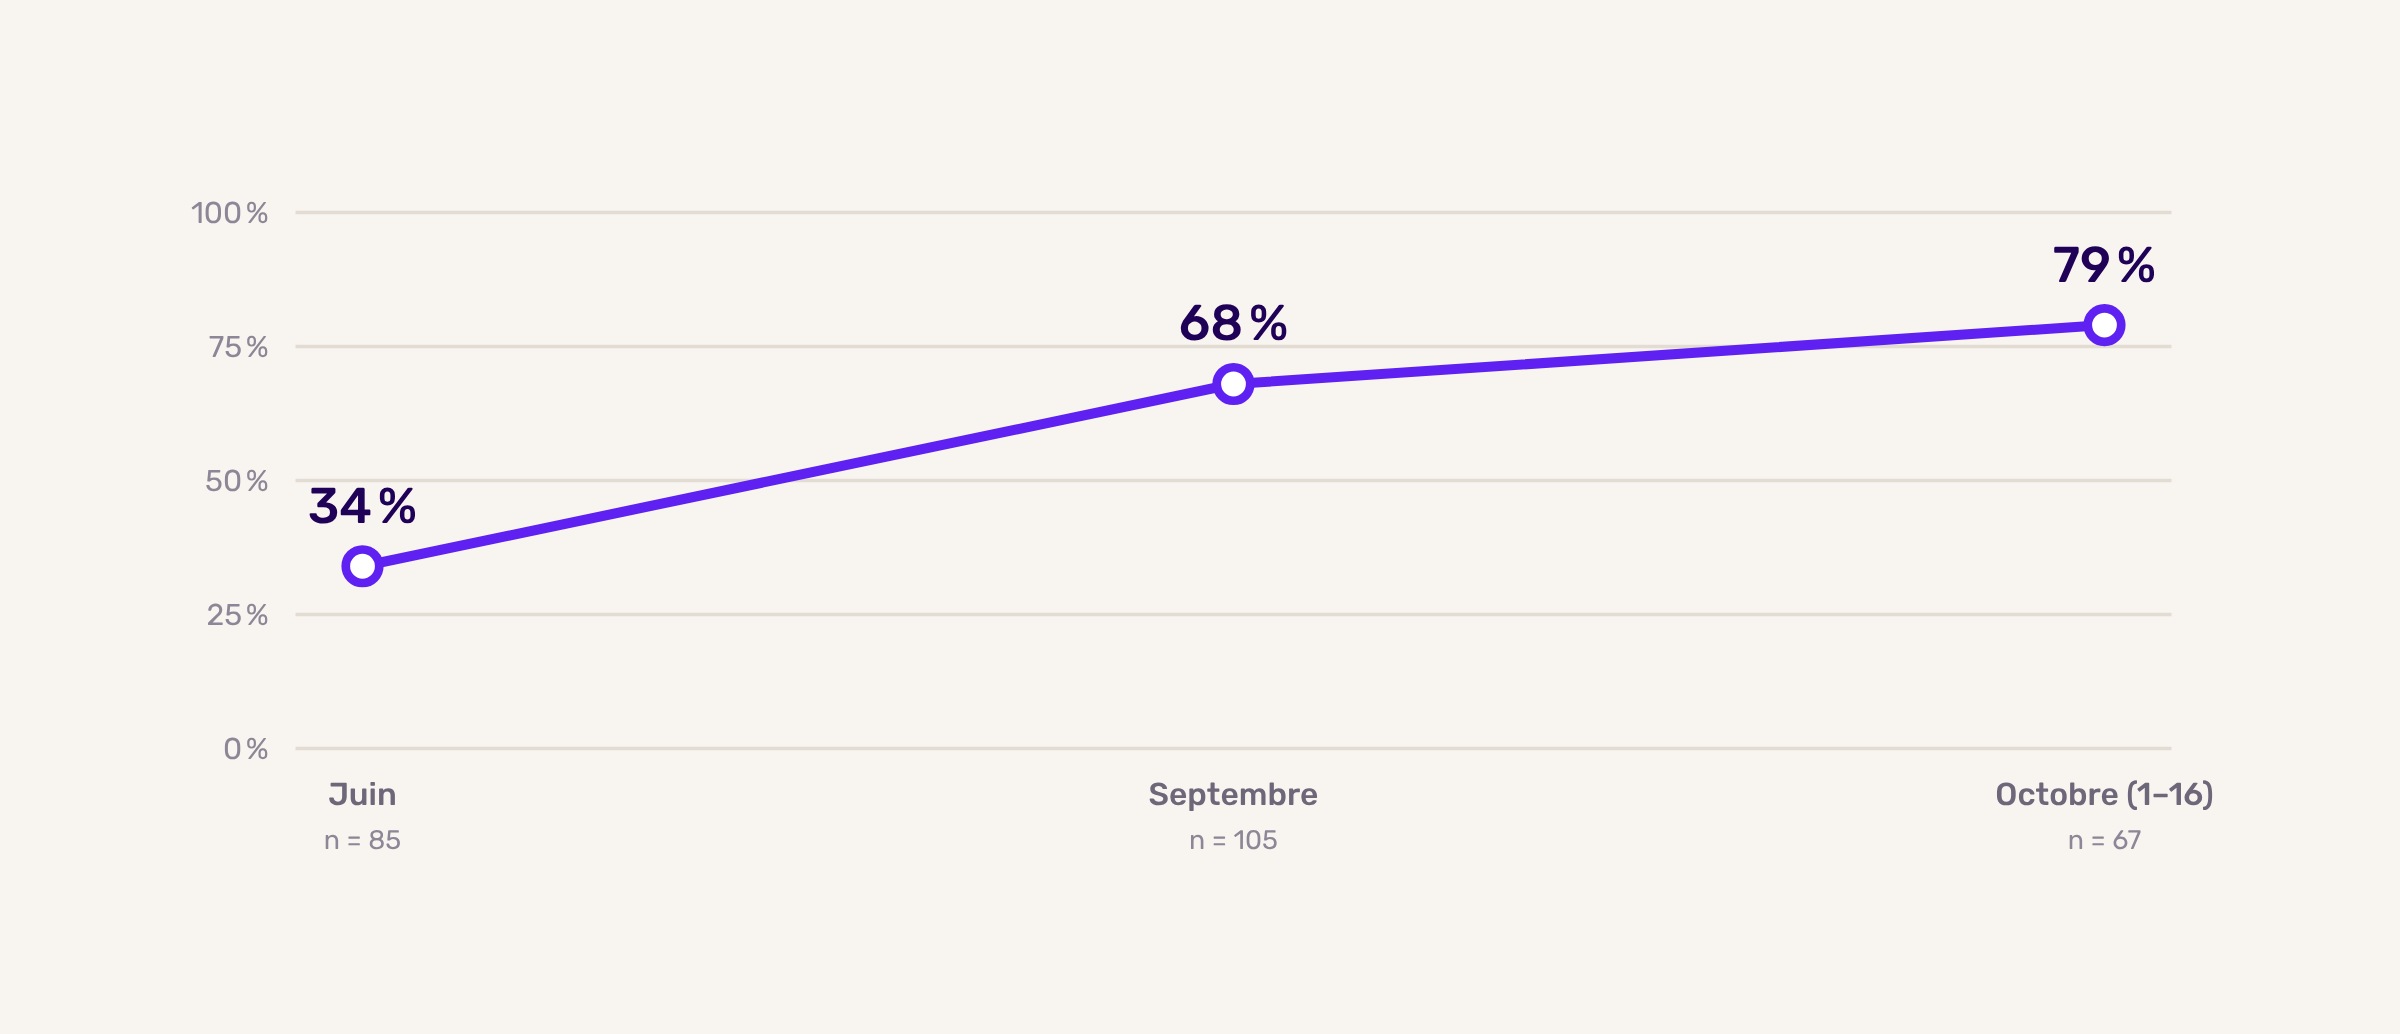
It's a simple indicator. It measures users' approval of the suggested text, not how well families understand it. Also, only users who respond are counted: at launch, about one in three gave their opinion, with a possible overrepresentation of the least satisfied. On the other hand, the measurement method stays the same from one version to the next, which makes it possible to compare versions of the AI and identify the one that gets the most favorable feedback.
Public sector: hosting in France, a mandatory requirement
When a measurement tool collects texts written by local government staff or teachers, the question of data hosting comes up from day one. For Edifice, the answer fits in one sentence:
“Hosting in France was simply a mandatory requirement for us.”
— Romain Gentet, Lead Product Manager, Edifice
This requirement didn't stay theoretical: Edifice's CISO reviewed Screeb's legal notices before the team approved the subscription. On Screeb's side, the guarantees come down to a few points:
- Hosting: 100% in France, with Scaleway and OVH.
- Jurisdiction: outside the CLOUD Act.
- Encryption: all exchanges are encrypted.
- Compliance: GDPR, ISO 27001 and AI Act.
- AI: feedback analysis relies on a French AI hosted in Europe (Mistral AI).
At Edifice, the texts collected to understand the feedback are pseudonymized. For teams working with the public sector, getting the measurement tool's hosting and legal notices approved upfront is essential, before configuring the first questionnaire. The details are on the data security page.
Measuring the quality of your AI with Screeb: Edifice's method
Since that first experiment, the method has been reused several times at Edifice. Romain's advice to a team launching an AI feature comes down to one idea: in some cases, asking users directly for their opinion is more useful and quicker to set up than building complex measures from browsing data.
Each step relies on a Screeb feature:
- Trigger the survey on a product event. Send Screeb an event at the right moment (for example “AI result displayed”), and the survey appears right after, with the targeting and frequency rules that keep you from over-surveying users. It can also be launched directly from your code, at the exact moment you want.
- Keep a light format with the survey builder. One rating question, then one or two open-ended questions: few steps to set up, little friction for the user.
- Link the response to what the AI produced with hidden fields. Pass the input text and the generated text when the survey launches: they attach to each response, without the user seeing them.
- Read the open-ended answers by theme with content analysis. Tone, register, length: the comments point to what needs adjusting. Screeb's customer feedback analysis surfaces the recurring themes in your feedback, with sample answers for each.
- Change it, then measure again in the survey results. Change the prompt or the model, and track satisfaction month after month on the same survey. If you send the prompt or model version as a property, you can also segment the results to compare before and after.
FAQ: measuring satisfaction with an AI feature
How do you measure satisfaction with an AI feature?
By asking users directly in the application, right after the AI result is displayed. Edifice uses a Screeb survey with a thumbs up or down, followed by open-ended questions to understand what can be improved.
What's the right moment to trigger a survey on an AI?
A few seconds after the AI's response. At Edifice, the survey appears about 10 seconds after the generated text, which gives immediate feedback that is unambiguously tied to the right feature.
Do you need complex usage metrics to judge the quality of an AI?
Not always. According to Romain, asking users directly for their opinion is in some cases more useful and quicker to set up than building adoption measures from browsing data.
How do you link a satisfaction score to what the AI produced?
By attaching to each response the text entered by the user and the generated version. Edifice collects them in pseudonymized form, which makes it possible to understand why a result is liked or disliked and to improve the prompt.
Can you measure the quality of an AI in the public sector?
Yes, as long as you meet the data requirements. For Edifice, hosting in France was a mandatory requirement, and its CISO reviewed Screeb's legal notices before approving the subscription. Screeb hosts its data 100% in France, with Scaleway and OVH.
Conclusion: measuring is already improving
In a few months, Edifice went from 34% to 79% satisfaction with its FALC rewriting AI, relying on simple measurement: a Screeb survey displayed at the right moment, the before and after texts to understand each piece of feedback, and prompt and model adjustments guided by users. All in a public-sector setting, with hosting in France required from the start.